Key Takeaways
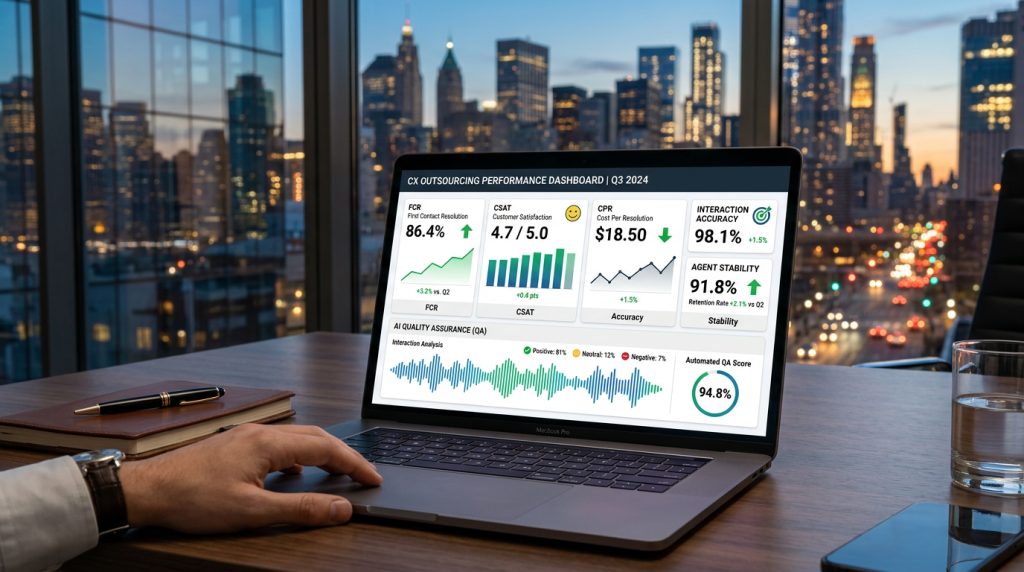
- Most outsourced CX programs track too many metrics and act on too few; a lean, connected stack built around FCR, CSAT, cost per resolution, accuracy, and agent stability is designed to give leadership real decision making visibility.
- When you move work offshore, physical visibility disappears and data becomes your primary management tool, so metric definitions, sources, and review cadence have to be designed up front, not inherited from old in house dashboards.
- AI QA coverage on 100 percent of interactions changes what is measurable, turning quality monitoring from a sampling exercise into a continuous system level signal, as long as raw outputs are translated into a small, stable set of leadership metrics.
- Hitting individual targets in isolation can quietly erode overall performance; programs that connect customer impact, economics, and operational health into a single framework are better able to spot trade offs and prevent metric gaming.
- The metrics that belong in a contract are not the same as the metrics leaders need on their dashboards; separating SLAs, shared scorecards, and internal KPIs prevents compliance reporting from crowding out decision ready information.
- A modern CX outsourcing system uses AI QA, three layer metrics (business impact, customer impact, operational health), and a disciplined governance cadence to make outsourcing safer and more transparent, not riskier and opaque.
Article at a Glance
Most outsourcing relationships do not fall apart because the vendor is incapable of executing. They break down because nobody defined success in a way that matches how leadership actually runs the business. By the time that becomes obvious, you are looking at a crowded dashboard, a contract full of SLAs, and a gap between what the numbers say and what customers are experiencing.
This article lays out a metrics architecture built for outsourced CX programs that rely on offshore teams and AI QA. It explains why the usual mix of service level, AHT, and sampled QA scores is not enough, and it shows how to connect five core metrics with AI driven reporting so you can see how customer experience, cost, and risk move together.
The focus is practical and system level. You will see how to design shared scorecards, decide what belongs in the contract versus weekly reviews, and use AI QA without drowning in data. Short scenarios from retail, utilities or healthcare, and SaaS helpdesk environments illustrate how leaders use this structure to make real decisions under pressure.
The intent is straightforward: give operations and CX leaders a way to redesign metrics so that outsourcing becomes an extension of their management system, not a blind spot they hope stays on track.
The Metrics Problem Every Outsourcing Leader Eventually Runs Into
Three months into an outsourced CX program, a pattern shows up across many organizations. The vendor is hitting every SLA. The dashboard lists more than twenty metrics. Yet complaints are creeping up, internal teams are spending more time than expected managing the relationship, and nobody can point to a single number that explains what is going wrong.
This is not just a vendor performance issue. It is a metrics design issue. The metrics in play were selected because they were easy to measure, familiar from prior programs, or required by procurement language. They describe operational throughput. They do not show whether customers are being served well or whether the program is delivering the business outcomes leadership expects.
The Vanity Metrics Trap
Operational metrics such as service level, average handle time, and abandonment rate are not useless. They are necessary signals for running a contact center. The trap is treating them as the primary lens for evaluating an outsourced program.
- Service level shows how quickly calls are answered, not whether they are resolved.
- AHT shows how long interactions take, not whether customers leave satisfied.
- Volume handled shows how busy the team is, not whether those contacts should have happened at all.
- Sample based QA scores show quality for a small fraction of interactions, not for the full population.
- Survey response rates show which customers responded, not necessarily what the full customer base experienced.
A program can meet an 80/20 service level while first contact resolution quietly declines. AHT can improve while accuracy on complex inquiries erodes. Without a structure that links operational efficiency with experience and outcomes, these trade offs stay hidden far too long.
Why Leadership Dashboards and Contract KPIs Diverge
Contractual KPIs exist to define accountability and remedies. Leadership metrics exist to inform decisions. When the same list of numbers is asked to do both jobs, it usually does neither well.
- Contractual KPIs tend to be conservative and tightly defined so both parties can audit them.
- Leadership metrics need to be forward looking, diagnostic, and explicitly tied to business results.
If you use only contractual KPIs on your leadership dashboard, you get clean reports and poor decisions. If you rely only on leadership metrics in the contract, you get endless debates about definitions and remedies. A better approach separates three layers:
| Layer | Primary Purpose | Typical Metrics |
| Contractual SLAs | Floor level accountability and remedies | Service level, minimum QA score, attrition caps |
| Operational management | Day to day and week to week decision support | FCR, cost per resolution, accuracy, escalation, sentiment trends |
| Business impact | P and L and strategic evaluation | Conversion on key contacts, repeat contact rate, retention cues |
Deliberately designing these layers before work starts is one of the clearest structural improvements a CX leader can make.
The Case for a Lean, Well Structured Stack
The goal is not more metrics. It is fewer, better connected metrics that give clear signals at each layer. Many well run outsourced CX programs can be governed with fewer than twelve core metrics organized across:
- Customer impact.
- Operational economics.
- Workforce and quality health.
Everything else is either drill down detail or noise. The rest of this article focuses on how to design that stack and use AI QA to keep it honest.
From In House To Outsourced CX: How Visibility and Metrics Change
When your contact center is in house, a lot of risk is managed informally. You can walk the floor, listen to side conversations, and sense when something is off before it shows up in a report. Supervisors share context. QA teams know who needs extra listening that week.
None of that transfers automatically when you move to an offshore or remote outsourcing model. In a Philippines based environment or any remote delivery model, physical visibility disappears. What replaces it needs to be intentional.
What You Lose When You Cannot Walk the Floor
Informal visibility catches early warning signs:
- Agents asking the same question about a new product.
- A script change that is landing poorly with customers.
- A process change that is confusing agents and creating rework.
In an outsourced model, those signals only reach you if there is a channel for delivery team observations, AI driven sentiment and topic monitoring, and regular calibration sessions where patterns get raised. Without those mechanisms, you will only see issues once they are large enough to move lagging metrics like CSAT.
How Data Replaces Physical Visibility
A modern outsourced CX system replaces informal floor reading with three formal elements:
- Shared near real time operational dashboards accessible to both client and vendor teams.
- AI QA and analytics that cover 100 percent of interactions, surfacing patterns no sampling program can catch.
- A structured review cadence that devotes time to interpretation and action planning, not just reading numbers.
When those three elements are working together, physical distance becomes a manageable constraint. When they are weak or missing, outsourcing becomes a trust exercise rather than a managed system.
Three Structural Shifts Leaders Have to Recognize
Moving from in house to outsourced CX changes the metrics game in three structural ways:
- Shared accountability
Every critical metric requires a documented definition, a single source of truth, and a named owner across client and vendor teams. Ambiguity here turns into disputes later. - SLAs versus outcomes
SLAs set the floor. They do not define excellence. A vendor can hit every SLA and still underperform against the business case, which is why outcome metrics must sit alongside SLAs in governance forums. - Wrong target risk
Vendors will naturally optimize for whatever the contract and reviews emphasize. If those targets are poorly chosen or isolated, the operation can improve on paper while the experience deteriorates.
Designing metrics with these shifts in mind reduces the odds of being surprised six months into an engagement.
The Core Metrics Stack Every Outsourced CX Program Needs
A well structured metrics stack for outsourced CX covers three layers that interact:
- What customers experience.
- What the program costs and produces economically.
- How healthy the workforce and quality systems are.
Within that stack, five metrics show up as non negotiable across most programs:
- First Contact Resolution.
- Customer Satisfaction or an equivalent interaction level satisfaction metric.
- Cost per Resolution.
- Accuracy Rate.
- Agent Stability, usually measured through attrition and shrinkage.
These are not the only metrics worth tracking, but they form the backbone that ties experience, cost, and risk together.
The Five Non Negotiable Metrics
First Contact Resolution (FCR)
FCR measures whether the customer’s issue was resolved without follow up calls, escalations, or channel hopping. It sits at the intersection of experience and cost. Strong FCR usually signals solid process design and training. Directional benchmarks in voice programs often fall between 70 and 80 percent, but the right target depends heavily on complexity and vertical.
Customer Satisfaction (CSAT or equivalent)
CSAT captures how the customer felt about the interaction. It does not always track perfectly with FCR, but together they show whether issues were resolved and whether customers felt well served in the process.
Cost per Resolution
Cost per resolution accounts for the economic effect of repeat contacts. Cost per contact alone can make a program look efficient while hidden rework costs are piling up. Leadership needs to see the cost required to reach resolution, not just the cost of handling calls.
Accuracy Rate
Accuracy rate tracks the percentage of interactions where agents provided correct information and followed required processes. It is especially important in regulated environments, where errors carry regulatory exposure and high downstream rework cost.
Agent Stability
Agent stability, captured through attrition and shrinkage, is a leading indicator of quality performance. In offshore models, annual attrition below a manageable threshold tends to support stable FCR and accuracy. High attrition pushes programs into a constant training mode and erodes institutional knowledge.
How These Metrics Interact
These metrics are tightly linked:
- Rising attrition often precedes FCR decline, which then raises cost per resolution.
- Declining accuracy increases error rate and compliance risk, which may not hit CSAT immediately but will eventually.
- Improving FCR without cost movement suggests escalation handling or repeat contact definitions need review.
Looking at any one of these in isolation leaves gaps. Tracking them together, with explicit attention to how changes in one drive changes in others, gives a more honest view of program health.
How AI QA and Full Coverage Monitoring Reshape Measurement
Traditional QA programs review only a small fraction of interactions. Supervisors and QA teams do what they can within the practical limits of listening time. Decisions about training and risk are often based on two to five percent of total volume.
AI QA changes that dynamic. When 100 percent of interactions can be evaluated against a defined rubric, measurement itself shifts from estimation to system level observation.
What AI QA Makes Possible
With full coverage AI QA, several categories of measurement become reliably available:
| Dimension | Under 2–5% Sampling | Under 100% AI QA Coverage |
| QA score reliability | Directional, high variance | Statistically stable, agent and topic level |
| Compliance language adherence | Sample based, reactive | Continuous, proactive, every interaction |
| Customer sentiment trends | Inferred from limited survey responses | Measured across all interactions by type and agent |
| Root cause of repeat contacts | Manual investigation required | Topic level pattern detection at scale |
| Coaching prioritization | Based on observation or random samples | Data driven, focused on patterns with largest impact |
The practical leadership implication is simple: you can stop guessing where to focus your attention.
Translating AI Outputs into Leadership Metrics
Raw AI QA output is dense. Without translation, it overwhelms. The discipline is to select a small set of AI derived metrics that appear on leadership dashboards consistently, with clear rules about when additional patterns are escalated.
Typical AI driven leadership metrics include:
- Aggregate QA score trend.
- Compliance flag rate by contact type.
- Sentiment trend index over time.
- Topic level repeat contact rate.
- Coaching completion rate tied to AI flagged behaviors.
Everything else stays in the operations layer for drill down use. Leadership sees the signals that matter for risk, experience, and quality health, not every detail the system can generate.
AI QA and Coaching Economics
AI QA improves coaching economics by clarifying where supervisor time moves the needle:
- If a particular closing pattern correlates with higher repeat contacts, coaching can zero in on that behavior.
- If sentiment consistently drops in the final minute of calls, AHT pressure and closing scripts can be revisited.
- If compliance omissions cluster by topic, SOPs and targeted training can be updated.
Coaching still needs human judgment. Supervisors should listen to representative calls and use AI data as a prioritization tool, not a substitute for context. The combination of AI pattern detection and human coaching is where programs see the clearest movement in FCR, CSAT, and cost per resolution.
Customer Impact Metrics Customers Actually Feel
Customers experience outcomes, not dashboards. The metrics they feel most directly are the ones that determine whether they stay, complain, or leave.
First Contact Resolution as a Customer Signal
FCR is often the single most telling customer experience metric because it captures whether the customer’s problem got solved without extra effort.
Key practical points:
- FCR below a reasonable range for your complexity level usually signals process or authorization gaps, not just training issues.
- FCR above a strong target is a sign of robust SOPs and empowered agents, especially in higher complexity programs.
- FCR definitions must be customer centered: a contact marked resolved that generates a callback within a defined window should not count as resolved.
- Segmenting FCR by contact type exposes which processes are underperforming rather than burying problems in an overall average.
Agree on the definition before go live. Relying on agent disposition codes alone invites overstatement and disputes later.
CSAT, NPS, and Customer Effort Score
Different satisfaction metrics answer different leadership questions:
- CSAT is interaction level and operationally useful for trending performance by queue, agent, or process change.
- NPS is relationship level and more relevant to strategic loyalty discussions than day to day CX management.
- Customer Effort Score works well where the goal is friction reduction, such as utilities or healthcare, where customers mostly want “easy and correct.”
These metrics should be interpreted in context, not treated as interchangeable.
Why Benchmarks Are Directional
Industry benchmarks are helpful starting points, not performance contracts. A CSAT level that is strong in a complex, regulated environment may be unremarkable in a simple retail support context. Similarly, FCR expectations vary meaningfully by complexity, channel, and the scope of authority granted to agents.
Use benchmarks to orient. Use your own pre outsourcing baseline to set realistic improvement targets and to evaluate whether the program is actually moving performance in the directions that matter for your business.
AI Sentiment and Topic Analysis as a Complement
Survey response rates are limited. A small percentage of interactions drives most CSAT data. AI sentiment analysis applied to all interactions broadens the view:
- Sentiment by contact type.
- Sentiment by agent tenure or cohort.
- Sentiment shifts after product or process changes.
The most effective programs use both: surveys to capture explicit customer feedback, and AI sentiment and topic analysis to understand emotional and content patterns at scale.
Economic and Efficiency Metrics That Tie CX to the P And L
For CX outsourcing to hold its place on the leadership agenda, it has to show clear economics. Leaders need to see how the program affects total cost of service, not just unit costs.
Cost per Contact versus Cost per Resolution
Most BPO reports emphasize cost per contact because it is straightforward to calculate. Cost per resolution requires understanding repeat contact behavior and escalation dynamics, but it is the more honest measure for leadership.
- A low cost per contact with high repeat contact rate can hide an expensive operation.
- A slightly higher cost per contact with strong FCR and low escalations often produces a lower total cost per resolved issue.
Tracking both metrics together reveals whether apparent efficiency is real or just shifting costs between contacts.
Average Handle Time as a Controlled Lever
AHT is critical for capacity planning and staffing. It becomes risky when it is used as a primary performance target without counterbalancing metrics.
When AHT is pursued in isolation:
- Agents may rush calls, skip verification questions, and avoid deeper diagnosis.
- FCR declines, repeat contacts increase, and CSAT falls, sometimes after a lag.
AHT belongs in the operational health layer as a managed lever, not as a standalone success metric. It needs to be reviewed alongside FCR and CSAT so trade offs are visible.
Self Service Containment as a Financial Indicator
When AI assisted self service and bots are part of the delivery design, containment becomes a direct economic metric.
The key is to measure:
- Containment based on resolution, not just deflection.
- Relationship between containment and live contact volume.
- Impact on cost per resolution across channels.
Customers who bounce from failed self service into live channels are not being contained; they are experiencing delay and frustration that eventually shows up in sentiment and CSAT.
Using AI QA to Target Coaching Where It Moves Economics
AI QA makes it possible to see how specific behaviors affect economic metrics:
- A closing pattern linked to higher repeat contact rate.
- A particular misrouting behavior that drives unnecessary escalations.
- A process step consistently skipped under time pressure.
When coaching is directed by clear links between behavior patterns and cost, leadership can justify investment in supervisor time, training adjustments, and SOP changes as part of an explicit economic plan, not just a quality initiative.
Quality and Workforce Stability Metrics That Protect Risk
Quality and workforce metrics act as an early warning system for risk. In regulated sectors, they also help protect against compliance exposure.
QA Scores, Error Rates, and Compliance Flags
QA scores gain real value when:
- Coverage is high enough to reduce variance.
- Scoring rubrics are clear and calibrated.
- Trends are analyzed by contact type, cohort, and time, not just in aggregate.
Two specific metrics deserve leadership attention alongside QA scores:
- Error rate for incorrect information or process execution.
- Compliance flag rate for missing required language or steps.
In a full coverage AI QA environment, these metrics can be monitored in near real time, allowing intervention at the pattern level rather than after a long tail of issues has accumulated.
Agent Attrition and Shrinkage
High attrition does not always show up immediately in customer metrics, but it steadily erodes program capability:
- New agents take longer to reach target FCR and accuracy.
- Supervisors spend more time on onboarding and less on coaching.
- Institutional knowledge about edge cases and nuanced handling drains away.
Shrinkage amplifies these effects by altering staffing assumptions and creating more frequent understaffed periods where speed pressure rises and quality slips. Leadership dashboards should show attrition trends, shrinkage patterns, and their correlation with FCR, CSAT, and error rates.
How AI QA Changes Calibration
Traditional calibration focuses on aligning human QA reviewers. In an AI QA model, calibration expands to:
- Reviewing AI scoring behavior on sampled calls.
- Adjusting rubrics when consistent differences between AI and human judgments appear.
- Clarifying how AI outputs feed into coaching and reporting.
This shifts QA from a manual scoring function to a hybrid analytical function, where people and tools work together to protect quality and risk standards.
Turning Metrics into a Governance System, Not a Scoreboard
A metrics stack only creates value if it drives decisions. That requires governance: cadence, ownership, and escalation paths built around the numbers.
Building a Review Rhythm That Works
A practical cadence for most outsourced CX programs looks like this:
- Daily: operational dashboards for queue performance, service level, abandonment, and critical AI QA alerts, used by operations teams for same day decisions.
- Weekly: FCR and QA trend review, AI derived patterns, agent level performance, and coaching actions; used by operations leaders from both sides.
- Monthly: CSAT, cost per resolution, attrition, error and compliance flag trends; used in joint business reviews with client operations and vendor leadership.
- Quarterly: program impact versus baseline and business case, used for strategic evaluation, scope decisions, and target adjustments.
Every review tier should have an explicit agenda, and each metric on that agenda should have a named owner responsible for interpretation and action.
What Belongs in the Contract versus Shared Dashboards
Contractual SLAs should focus on a small handful of metrics where falling below a threshold requires formal remedies:
- Service level.
- Minimum QA score.
- Maximum attrition rate.
- Uptime for any vendor operated technology.
Shared dashboards should be broader and diagnostic, including FCR, cost per resolution, accuracy, sentiment, repeat contact rate, and AI QA metrics. These are the tools both parties use to run the program day to day.
Internal KPIs can remain separate where appropriate. For example, links between CX performance and customer lifetime value may be tracked internally even if the vendor is not directly accountable for those outcomes.
Guarding Against Goodhart Effects
When a measure becomes a target, it tends to lose its value as a measure. In CX outsourcing, this shows up when:
- AHT falls while FCR and CSAT decline.
- QA scores rise on sampled calls but AI sentiment trends stay flat or decline.
- FCR improves on paper while repeat contact volumes rise.
The defense is structural:
- Always review core metrics together, not in isolation.
- Pair metrics that act as counterweights, such as AHT with FCR, or QA score with sentiment.
- Use AI QA coverage to make performance consistent across reviewed and unreviewed interactions.
Business review conversations should explicitly ask where improvements in one metric may be creating hidden costs in another.
Designing Executive versus Operations Dashboards
Executives and operations leaders need different views:
- Executive dashboards should focus on trends for FCR, CSAT, cost per resolution, attrition, and compliance or error flags, with clear commentary on direction and implications.
- Operations dashboards should provide real time visibility into queues, agent level performance, coaching status, and AI QA alerts.
Both layers should draw from the same underlying data. They should not be the same report.
AI driven reporting can surface patterns without overwhelming leadership if it is used to:
- Highlight a small number of priority patterns.
- Flag anomalies instead of listing all movements.
- Structure summaries that can be reviewed meaningfully in fifteen minutes.
The question every report should help answer is: what needs to change next week.
Metrics Cadence Across the Lifecycle of an Outsourced Program
Metrics needs change as a program moves from evaluation to pilot to steady state. A fixed metrics design that ignores lifecycle stages will misjudge early performance and under manage mature programs.
Evaluation and Contracting: Baselines First
Before outsourcing begins, leadership should document:
- Current FCR, CSAT, cost per contact, accuracy, and attrition, or the closest available proxies.
- Variations in these metrics by contact type, complexity, and channel.
These baselines allow you to distinguish between programs that are truly improving performance and those that look good only against generic benchmarks. They also form the basis for realistic targets and timelines.
The 30 to 90 Day Pilot Window
The first 30 to 90 days are a learning phase. The right metrics emphasis is:
- Trend direction for FCR, not absolute target attainment.
- Movement in compliance flag rate and error rate, not just averages.
- Repeat contact and escalation patterns by topic.
Programs that show positive trends on leading indicators during this period are usually well positioned for steady state performance. Flat or negative leading indicators this early often point to process documentation or scope issues that need structural work.
Stabilization and Steady State
Once FCR, QA, and accuracy have been stable for a period and attrition has normalized, you can:
- Raise targets selectively where headroom exists.
- Use AI QA data to identify specific behaviors or process steps limiting performance.
- Shift more of the conversation in governance forums toward continuous improvement.
Resist the urge to raise every target at once. Incremental changes with targeted support are more likely to stick.
Revisiting Targets After Changes
Any significant change in scope or design should trigger a target review:
- New channels or contact types.
- Major product or policy changes.
- New AI capabilities, such as expanded self service.
Including a formal “metric and target review” step in change management processes keeps goals aligned with reality rather than locked to outdated assumptions.
A Practical Metrics Framework Leaders Can Apply
All of these ideas can be pulled into a single, practical model: a three layer metrics framework for outsourced CX programs.
The CX Outsourcing Metrics Ladder
The framework organizes metrics into:
- Business impact
Cost per resolution, conversion on service to sales contacts, repeat contact rate as a driver of total cost, and retention signals where available. - Customer impact
FCR, CSAT or equivalent, and accuracy rate. - Operational health
Agent attrition and shrinkage, QA score trend, compliance flag rate, AHT balanced with FCR, and other workforce indicators.
A program that watches all three layers together can see:
- Whether CX is delivering on the financial case.
- Whether customers are being well served.
- Whether the underlying operation can sustain or improve current results.
Ignoring any one layer creates blind spots that eventually show up as surprises in the others.
Six Questions to Test Your Current Metrics Stack
Leaders can stress test their existing metrics setup with six questions:
- Are metric definitions documented and shared, including calculation methods and data sources?
- Can you trace clear links between operational metrics, customer metrics, and business impact metrics in your data?
- Do you have a reliable baseline from before outsourcing that you can use to evaluate changes?
- What proportion of interactions does your current QA program cover, and is it enough for your risk profile?
- Does your governance cadence include a standing check for metric trade offs and Goodhart effects?
- Are leadership and operations dashboards designed differently for their distinct decision needs?
The goal is not to achieve a generic ideal, but to ensure your metrics design is deliberate and fit for your particular program.
How the Framework Prevents Over Indexing on a Single Number
The framework makes it structurally harder to fixate on one metric:
- CSAT cannot be celebrated in isolation if attrition and error rates are trending poorly.
- FCR gains are evaluated alongside cost per resolution and escalation behavior.
- Cost metrics are considered alongside customer impact and operational resilience.
This structure also gives CX leaders a sharper narrative in executive forums: here is what the program is doing for the business, here is what customers are experiencing, and here is the health of the engine producing those results.
Checklist for Setting Metrics in a New Outsourced CX Agreement
Designing metrics up front saves months of friction later. A targeted checklist helps keep the negotiation focused on what will matter once calls are flowing.
Aligning on Definitions, Sources, and Ownership
Before go live, ensure that:
- Each metric has a clear written definition and formula.
- The system of record for each metric is identified and agreed.
- Responsibilities for report production, review, and escalation are assigned.
This is especially important for metrics such as FCR, AHT, and cost per resolution, where subtle definition differences can materially change the reported outcome.
Specifying AI QA Coverage and Governance
Where AI QA is part of the program, document:
- Target coverage level as a percentage of interactions.
- The rubric the AI uses and who owns updates.
- Calibration frequency and process, including human review of AI scoring.
- The process for agents or supervisors to challenge scores and request exception review.
These elements protect trust in the system and ensure AI generated metrics are accepted as legitimate by both front line teams and leadership.
Avoiding Common Contracting Pitfalls
Watch for structural choices that create blind spots:
- Turning every dashboard metric into a contractual SLA.
- Leaving FCR definitions entirely to vendor interpretation.
- Omitting attrition thresholds from the agreement.
- Failing to specify baseline measurement periods.
- Not formalizing reporting cadence and formats.
Start from the information leadership needs and design the contract and reporting model to serve that, rather than starting from a default vendor dashboard.
Using AI QA to Strengthen Metrics Without Drowning in Data
AI QA is powerful, but only if it is treated as a signal filter, not a raw data feed.
What AI QA Monitors at Scale
At full coverage, AI QA can reliably monitor:
- Compliance language adherence on every contact.
- Sentiment shifts across contact types, agents, and time.
- Topic level patterns in repeat contacts and escalations.
- Script adherence on key steps that drive resolution and risk.
These capabilities allow leaders to move from occasionally sampling areas of concern to continuously observing them.
Translating Data into a Manageable Set
The translation step is critical. A practical approach is to define:
- A stable set of five to seven AI derived leadership metrics, as noted earlier.
- Thresholds for when non standard patterns trigger escalation.
This keeps leadership discussions focused on:
- Where risk is emerging.
- Where sentiment is shifting.
- Whether operational responses to AI findings are delivering improvements.
The rest of the AI data remains available for analysts and operations teams to answer “why” questions when patterns surface.
Governance for How AI Findings Enter Coaching
AI outputs should be governed by simple rules:
- AI identifies patterns and candidates for review.
- Supervisors review representative interactions before coaching.
- Coaching focuses on building capability, not just correcting scores.
This prevents misinterpretation of edge cases and protects agent trust in both supervisors and systems.
Short Scenarios: How Leaders Use Metrics to Steer Outsourced CX
The following composite scenarios illustrate how different leaders apply this metrics framework in practice.
Scenario One: Retail CX Leader Under Peak Season Pressure
A retailer working with a Philippines based CX team entered peak season with stable FCR and CSAT. As volume tripled, CSAT dropped sharply, even though service levels and AHT stayed on target.
AI QA revealed that sentiment was falling in the last minute of calls, and FCR was slipping because agents were rushing closings under volume pressure, skipping confirmation steps. The leader and vendor agreed on a temporary AHT relaxation for specific queues and rolled out targeted coaching on closing scripts.
Within weeks, sentiment and FCR trends recovered. The program still felt the strain of peak season, but the damage was limited and clearly understood, rather than mysterious.
Scenario Two: Utility or Healthcare Operations Leader Focused on Compliance
A regional utility outsourced billing and outage calls after internal consolidation. Traditional QA sampling caught occasional compliance omissions, but there was no clear pattern.
After implementing AI QA, the team saw a higher compliance flag rate on weekend outage calls. Root cause analysis showed that weekend shift briefings were missing a recent update to required disclosure language. The fix was to adjust the briefing process and documentation, not to launch a broad agent performance crackdown.
With full coverage QA, the compliance risk surface became visible early and was addressed structurally.
Scenario Three: SaaS Helpdesk Leader Balancing Complexity and Speed
A B2B SaaS firm outsourced tier one helpdesk support while retaining higher tiers. Finance pushed for aggressive AHT targets, but FCR plateaued well below the desired level.
AI topic analysis showed many contacts being closed at tier one without resolution because tier one agents lacked access to necessary account details. Once read only access and updated SOPs were rolled out, FCR improved materially without any increase in AHT.
The metrics framework made it clear that the constraint was process design and access, not agent performance, and the fix produced both customer and economic benefits.
Frequently Asked Questions from CX and Operations Leaders
Which Metrics Truly Matter in an Outsourced CX Program?
The metrics that matter are those that provide consistent visibility across business impact, customer impact, and operational health. For most programs, a core set of five to seven metrics covers that need:
- FCR.
- CSAT or comparable satisfaction metric.
- Cost per resolution.
- Accuracy rate.
- Agent attrition, and where needed, shrinkage.
- Selected AI QA metrics such as compliance flags and sentiment trend.
Additional metrics should be treated as contextual tools, not the core of your governance model.
How Should Benchmarks Adjust for Industry, Complexity, and Channels?
Use industry benchmarks as starting points, then adjust based on:
- Your pre outsourcing baseline and contact mix.
- Complexity of common interactions.
- Regulatory risk profile.
- Channel mix across voice, chat, email, and self service.
High complexity and regulatory weight will usually lower the ceiling for FCR and CSAT compared to simpler contexts, and benchmarks must reflect that reality to be useful.
How Do AI and Automation Change What I Track and How Often?
AI QA and automation expand the range of metrics that can be trusted and allow faster review cycles:
- Quality and compliance metrics can be reviewed weekly or even daily with confidence when coverage is high.
- Sentiment and topic patterns become stable enough for regular leadership review, not just occasional analysis.
- Containment and deflection metrics for self service become core business indicators rather than side reports.
Programs that adopt these tools should revisit their review cadences and dashboard designs to take advantage of the new visibility.
What Should Go into SLAs versus Shared Scorecards or Internal KPIs?
SLAs should be reserved for a handful of floor level metrics where clear thresholds and remedies are essential. Shared scorecards should include the broader metrics both parties use to manage performance and improvement. Internal KPIs may build on these metrics but serve additional strategic purposes and do not always need to be part of vendor accountability.
Explicitly documenting which metrics live in each bucket avoids confusion and ensures governance conversations stay focused.
How Do I Prevent Vendors from Gaming Metrics or Optimizing the Wrong Things?
Structural defenses include:
- Tracking connected metric pairs so trade offs become visible.
- Using AI QA to reduce the difference between “reviewed” and “unreviewed” performance.
- Making Goodhart effects a routine discussion item in business reviews.
When vendors know you are watching system level patterns rather than isolated targets, the incentive to game a single number drops and collaboration on real improvements becomes easier.
How Often Should Targets and Dashboards Be Revisited?
Targets and dashboards should be reviewed:
- Quarterly for strategic fit and stretch, especially as the program matures.
- After any major change in scope, channel, or technology.
- Annually for an end to end check against evolving business goals.
Regular, predictable review cycles turn target adjustments into a normal part of governance rather than contentious one off negotiations.
How Do I Align Internal Stakeholders Around a New Metrics Model?
Use the three layer framework to speak each stakeholder’s language:
- Finance: business impact metrics such as cost per resolution and total cost of service.
- Operations: customer impact and operational health metrics such as FCR, accuracy, and workforce stability.
- Executive leadership: a concise narrative tying the three layers together.
Present the framework early, set baselines everyone recognizes, and stick to an agreed review rhythm. When stakeholders see their concerns reflected in the structure, alignment follows more naturally.
Using Metrics to Make Outsourcing Safer and More Transparent
The right metrics system can make outsourcing safer than in house operations by giving leaders clear, structured visibility across geographies and time zones. The wrong metrics system turns outsourcing into a leap of faith.
A strong outsourced CX environment uses:
- A lean, connected stack with FCR, CSAT, cost per resolution, accuracy, and agent stability at its core.
- AI QA and reporting to monitor quality and risk across every interaction.
- A three layer metrics framework that ties operational health to customer impact and business outcomes.
- Governance rhythms that turn data into decisions rather than into static reports.
From there, the next step is to translate these principles into your own environment: evaluate your current metrics stack, identify where it misaligns with this structure, and decide where to simplify, where to add, and where to redesign.
If you want to see how this kind of metrics architecture would look in your specific context, a focused review of your current dashboards, SLAs, and reporting cadence can be revealing. It is often enough to highlight a few high impact changes that materially improve visibility and confidence.
For organizations that want a deeper, structured look at how their current CX outsourcing metrics are performing, you can request a reporting sample and assessment aligned to your existing stack, customer journeys, and risk profile. The goal of that conversation is not to sell you on a generic model, but to map a metrics system that matches your volumes, processes, and ambitions while keeping compliance and operational risk in view.
Disclaimer: Any claims in this article are based on previous experiences with clients and differ from client to client. Optimize CEC cannot make a guarantee on results because they depend on factors including internal processes, organizational readiness, and execution quality.