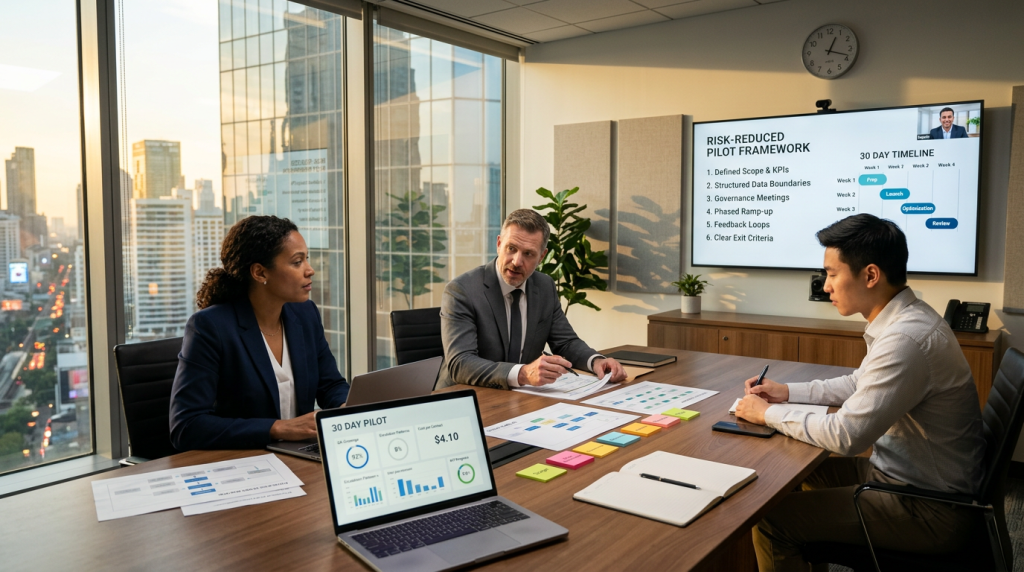
Key Takeaways
- Most outsourcing pilots fail because of process, governance, and scope decisions, not because offshore teams are inherently risky.
- A risk reduced 30 day pilot demands narrow scope, black and white procedures, clear data boundaries, and a single internal owner.
- Leaders should agree on success criteria, compliance protocols, and governance cadence before the pilot starts, not during week one.
- Tiered metrics non negotiable performance indicators plus diagnostic signals give a more honest view of fit than headline cost numbers.
- A well designed pilot creates reusable assets process maps, data flow documentation, QA routines that improve your operation even if you do not scale the vendor relationship.
Article at a Glance
Many leaders treat outsourcing pilots as low stakes trials, then discover they have exposed their brand, data, and frontline teams without enough structure. A hurried 30 day test that tries to do too much, with fuzzy scope and no baseline, is more likely to erode confidence than to validate the model.
The safest way to test an offshore partner is to treat the pilot as a governance exercise, not a discount offer. That means choosing a narrow slice of work, documenting how it should run, defining what data can and cannot move, and agreeing on how performance, exceptions, and compliance signals will be handled.
A risk reduced 30 day pilot is not about proving that offshore delivery can work in theory. It is about learning how your processes, systems, and culture respond when a new team participates in your day to day workflows under real constraints. The right design makes this learning concrete and reusable, whether you continue with the partner or not.
The sections that follow outline where pilots go wrong, what good looks like in a modern, governed pilot, a practical six decision framework for design, and scenarios and FAQs you can use to prepare your own organization for a safer first 30 days.
Why Outsourcing Pilots Feel Risky
Outsourcing touches brand, compliance, and internal politics in a way few other decisions do. Leaders worry about customers noticing accents or script reading, frontline staff feeling threatened, and regulators or internal compliance teams questioning data flows. Even a free pilot can feel like taking on risk without adequate control.
For many teams, the risk is less about the idea of offshoring and more about the memory of previous failed attempts. Pilots that launched without clear scope, with rushed training and vague metrics, left leaders with high complaint volumes, messy escalation paths, and no way to tell whether the vendor or the process was at fault. Those experiences shape how risky the next pilot feels.
When leaders cannot answer basic questions before the pilot begins what exactly will this team handle, how do we stop them from seeing sensitive data, who internally owns the pilot the perceived risk spikes. A structured design reduces that anxiety by making each of those decisions explicit and documented.
The Real Sources of Pilot Risk
Pilot risk rarely comes from geography alone. Instead, it comes from how process, data, and governance are handled when work moves beyond the internal team. Three structural issues drive most early failures.
First, undocumented or inconsistent processes leave offshore teams guessing. Tribal knowledge, edge case handling, and complex exceptions that internal staff manage informally do not translate well into a pilot. The offshore team applies their best judgment, outcomes are uneven, and internal teams blame the vendor instead of the underlying process.
Second, scope and volume assumptions are often unrealistic. Leaders ask a pilot team to handle too many call types or ticket categories at once, or expect them to absorb unpredictable peaks. When volumes swing or complexity creeps in, the pilot looks worse than the internal baseline, even though the test was set up to fail.
Third, governance and ownership are weak. Without a single internal owner and a defined cadence for reviews, issues surface through anecdote rather than structured reporting. Complaints travel faster than facts, and leaders end the pilot with more frustration than insight.
Where Process and Volume Assumptions Break
Resource planning in a pilot can create hidden risk if not grounded in reality. When leaders assume that volumes will stay flat, or that offshore teams can absorb fluctuating demand without clear triage rules, service levels suffer. Internal teams step in to patch gaps, and everyone ends the pilot feeling the model is unstable.
Process clarity matters just as much. If a ticket category looks simple on paper but in practice requires constant exceptions, judgement calls, or cross functional coordination, it is a poor fit for a first pilot. The right starting scope is repeatable, rules based work where success is easy to define and measure, and where exceptions can be routed back in house without confusion.
What a Well Designed 30 Day Pilot Looks Like
A good pilot feels less like a test of the vendor and more like a structured learning exercise for your operation. It starts with a narrow, clearly defined process lane, uses black and white procedures for that lane, and keeps sensitive interactions and complex exceptions in house. The offshore team knows exactly what they own and what they do not.
From a governance perspective, a well designed pilot has four phases. Week zero is design and baseline: scope selection, SOP documentation, data boundary definition, and capturing internal metrics. Week one focuses on supervised execution, with internal owners close to scripts, tools, and early QA. Weeks two and three settle into a stable cadence, where performance and exceptions are reviewed weekly and adjustments are made. The final week concentrates on decision preparation interpreting results, gathering qualitative feedback, and outlining options for extend, expand, or exit.
This design does not eliminate risk, but it makes it observable and manageable. Leaders see in real time how offshore agents work within agreed boundaries, how QA and reporting surface issues, and how internal teams experience the partnership. The pilot becomes a rehearsal for long term governance, not just a four week experiment.
Scope, Boundaries, and What Stays In House
Choosing what to include and exclude from a pilot is the most important design choice. The starting scope should focus on interactions or tasks that are:
- High volume and repeatable.
- Governed by clear rules and scripts rather than judgment calls.
- Low in direct regulatory sensitivity when handled correctly.
For a customer experience center, that might mean a single inbound call type with well defined resolution paths and a tight escalation rule back to internal staff. For a HelpDesk, it might mean tier one tickets where agents follow documented troubleshooting steps and escalate unresolved issues to internal tier two.
During the pilot, certain work should remain in house. That includes interactions that involve nuanced brand decisions, complex cross functional coordination, or regulatory grey areas where data handling or advice boundaries need more design. Keeping those in house reinforces the message that the pilot is a controlled test, not a wholesale shift.
How AI QA and Reporting Fit Into 30 Days
Quality assurance and reporting often change during a pilot. In many SMB environments, internal QA relies on sampling a small portion of calls or tickets. A pilot with full coverage QA whether through AI or systematic logging can produce a very different view of performance.
The first 30 days are less about achieving perfect QA scores and more about seeing patterns:
- Where do offshore agents deviate from scripts.
- Which scenarios produce more rework or escalation.
- How often potential compliance issues appear.
Simple dashboards that show these patterns each week help leaders distinguish between fixable issues training, documentation, scope adjustment and structural incompatibilities. They also demonstrate how continuous QA coverage could change management routines if the partnership scales.
The Pilot Design Framework
To make pilot risk manageable, leaders need a repeatable design framework. One practical way to structure this is around six decisions made before day one.
These decisions cover process boundaries, compliance handling, baselines, internal ownership, governance cadence, and definitions of success. When captured in writing, they form a compact pilot charter that anchors expectations for both internal and offshore teams.
Decision 1 Define the Process Boundary
The first decision is to define the process boundary in writing. That includes:
- What work the offshore team will handle.
- Inputs they receive and outputs they must produce.
- Clear exclusions, such as certain customer segments or interaction types.
- Escalation rules when a case falls outside the boundary.
Without this boundary, pilots drift. Offshore agents respond to whatever comes into the queue, exceptions multiply, and leaders cannot interpret performance because the work mix keeps shifting. A written boundary ensures that when data is reviewed, everyone knows what was actually tested.
Decision 2 Set Compliance Handling Protocol
Sensitive data and compliance topics must be treated as shared responsibilities. Before the pilot starts, leaders and vendors should agree on:
- Which data fields offshore teams can access.
- Which data elements must remain in house.
- How potential compliance issues are flagged and escalated.
- What training offshore agents receive on boundaries and escalation.
For areas like healthcare information, payment flows, or legal support, the language should emphasize alignment with requirements rather than ownership of compliance. Offshore teams support workflows within defined boundaries, while internal legal and IT teams remain responsible for setting those boundaries and reviewing adherence.
Decision 3 Establish Baseline Metrics
A pilot without baseline metrics offers little value. Leaders need to know current performance and cost for the scoped work before offshore teams begin. Baselines typically include:
- Cost per contact or cost per ticket for the selected scope.
- Accuracy and resolution rates based on internal QA.
- Cycle time from open to resolved.
- Customer experience indicators relevant to the scope.
These metrics allow leaders to compare pilot results to their own internal system rather than to vendor promises. They also highlight where process improvements inside the organization might be more impactful than outsourcing alone.
Decision 4 Assign a Single Internal Owner
Pilots work best when there is one internal owner with authority over scope, decisions, and communication. This owner:
- Coordinates training and knowledge transfer.
- Reviews weekly QA and performance data.
- Decides when to adjust scope or scripts.
- Communicates pilot status to other leaders.
Without a single owner, feedback fragments. Operations, finance, IT, and frontline managers interpret pilot signals differently, and no one is accountable for making the adjustments that would turn a noisy test into a clear learning exercise.
Decision 5 Set Governance Cadence With Your Partner
Governance during a pilot should be light but consistent. Leaders and vendors can agree on a weekly routine that includes:
- Review of key metrics for the scoped work.
- Discussion of exceptions, escalations, and compliance flags.
- Identification of training needs and knowledge base gaps.
- Agreement on adjustments for the coming week.
This cadence prevents minor issues from accumulating and being judged at the end of the pilot with limited context. It also gives both sides a chance to see how joint problem solving feels in practice, which is a useful signal for long term fit.
Decision 6 Define Success and Next Step Options
Finally, leaders should define what success looks like before the pilot begins and what options they will consider at the end. Success criteria usually include:
- Performance at or near baseline on core metrics.
- Clear improvement in QA visibility or reporting quality.
- Evidence that the vendor respects data boundaries and escalation rules.
- Positive qualitative feedback from internal teams on communication and collaboration.
Next step options might include extending the pilot, expanding scope gradually, or exiting while preserving the process assets created. Agreeing on these options in advance keeps the decision from being driven solely by one metric taken out of context.
What To Measure In The First 30 Days
Measurement in a pilot should focus on both non negotiable performance metrics and diagnostic signals. Leaders need enough data to make a responsible decision without expecting a full transformation in four weeks.
A practical way to organize measurement is to separate tier one metrics the core indicators of success from tier two metrics the signals that explain why performance looks the way it does.
Tier One Metrics The Non Negotiables
Tier one metrics reflect the minimum performance standards for the scoped work. They often include:
- First pass accuracy or correct resolution rate.
- Resolution or closure rate within agreed timelines.
- Average handling time or cycle time compared to baseline.
- Basic customer experience indicators for the pilot slice.
These metrics answer the question: does this pilot show that offshore delivery for this specific scope can match or reasonably approach current performance without introducing new risk. Leaders should expect some variation during the pilot, but large gaps signal issues that need deeper review.
Tier Two Metrics Diagnostic Signals
Tier two metrics help diagnose why tier one metrics look the way they do. Useful signals include:
- Exception rate how often cases fall outside the documented process.
- Rework rate how many interactions require multiple touches to resolve.
- Escalation patterns where work flows back to internal teams.
- Coaching and QA issues identified during reviews.
These signals highlight whether problems stem from scope choices, documentation, training, or fit. For instance, a high exception rate might indicate that the selected process is less black and white than leaders thought, suggesting a different starting scope would be safer.
What Not To Optimize During A Pilot
A common mistake is trying to optimize everything in the first 30 days. Leaders chase lower costs, higher volumes, and complex cross functional workflows before the basics are stable. That approach usually produces noisy results and frustrates internal teams.
During a pilot, some areas should be treated as secondary:
- Aggressive cost reductions across the broader function.
- Complex SLA structures that assume steady state behavior.
- Large scale automation changes that alter workflows mid pilot.
Treat the pilot as a chance to validate fit, governance, and process clarity for a narrow slice of work. Once those elements are proven, scaling and optimization decisions can be made from a more informed position.
Pilot Scenarios How Different Organizations Approach 30 Days
Short scenarios can help leaders visualize what a risk reduced pilot looks like in practice. The details will differ by organization, but patterns often repeat.
Scenario 1 CX Contact Center Starting With One Call Type
A retail company with a 40 agent contact center decides to pilot offshore support for a single inbound call type order status. The work is rules based, has limited compliance sensitivity, and represents a meaningful share of volume.
Leaders define a clear process boundary: offshore agents handle initial status checks, scripted updates, and defined escalation triggers when orders are delayed or complex. Sensitive billing questions and complaints remain in house. Baseline metrics show current handling time, resolution rate, and customer satisfaction for this call type.
During the pilot, QA covers all order status calls taken by offshore agents. Weekly governance meetings review exceptions, training needs, and any early warning signals. At the end of 30 days, leaders see that accuracy and satisfaction are within an acceptable range, while internal staff report less time spent on routine questions. That combination supports a gradual expansion of scope.
Scenario 2 HelpDesk Pilot On A Narrow Ticket Slice
A mid sized utilities provider considers outsourcing part of its IT HelpDesk. Instead of handing over all tickets, it selects a narrow slice tier one password resets and basic access issues. These tickets have clear playbooks and limited risk when handled correctly.
The process boundary defines inputs, standard scripts, and escalation rules when problems fall outside basic reset patterns. Offshore agents receive training on tools and access protocols, with system permissions configured to limit what they can see. Baseline metrics show current resolution time and the volume of tickets per week.
Over 30 days, leaders monitor resolution rates, exception patterns, and feedback from internal IT staff. They learn that offshore agents handle the selected tasks reliably, but that documentation for certain edge cases needs improvement. The pilot leads to better playbooks and gives leaders confidence to consider additional tier one tasks while keeping tier two and sensitive system changes internal.
Scenario 3 Backoffice Work With Strict Data Rules
A healthcare oriented company wants to test offshore backoffice support for claims data entry, but is rightly cautious about patient information. It designs a pilot where offshore teams work with masked data fields and structured templates rather than full records.
Internal teams define which fields are visible, which are abstracted, and how completed work is checked before being merged into core systems. QA focuses on accuracy of data entry and timeliness, while compliance oversight ensures that boundaries are respected.
The pilot demonstrates that offshore teams handle repetitive, rules based entry work well within the defined boundaries. Leaders gain a clearer view of which parts of the workflow can be safely offloaded and which must remain under tighter internal control.
Frequently Asked Questions About 30 Day Pilots
How much internal time does a 30 day pilot require
A realistic pilot requires committed internal time from operations, IT, and frontline leaders. Designing scope, documenting processes, configuring systems, training offshore agents, and reviewing weekly performance will take meaningful effort. In many environments, this looks like several hours per week for the pilot owner, plus structured participation from other stakeholders. Treating the pilot as a serious project rather than a side experiment usually produces better outcomes.
What if our processes are not fully documented
Many teams start pilots without complete documentation, which increases risk. If processes are messy or rely on tribal knowledge, leaders can still proceed by narrowing scope to the most rules based tasks, documenting those specifically, and using the pilot to highlight where additional documentation is needed. It is better to delay or narrow a pilot than to launch a broad test on undocumented workflows.
Can sensitive customer or patient data be handled safely
Sensitive data requires explicit boundaries and shared responsibility. Pilots should begin with clear rules on what data offshore teams can access, how it is protected, and when it must be escalated or kept in house. For areas like healthcare information or payment flows, alignment with requirements is discussed case by case with legal and IT teams, and pilots stay at a level where both sides are confident about data handling.
What happens if performance dips during the pilot
Performance dips are common in early weeks as new teams learn processes and tools. The key is to distinguish temporary learning curves from structural issues. Weekly governance reviews can help identify whether dips are tied to training gaps, unclear documentation, or misaligned scope. Leaders can adjust scripts, add coaching, or refine boundaries rather than declaring the pilot a failure at the first sign of variance.
Is a free pilot genuinely free, or are there hidden setup costs
Free pilots usually remove direct financial cost for the test period, but they still require internal time, attention, and change management. Hidden costs often appear when internal teams are not prepared for the effort or when scope creeps beyond the original agreement. Clarifying responsibilities, deliverables, and limits upfront keeps the pilot focused and prevents surprises.
How do we exit or extend if the pilot is inconclusive
Not every pilot produces a simple yes or no answer. Leaders should design exit and extension options upfront. If results are mixed, one path is to extend the pilot with adjusted scope or improved documentation to get clearer data. Another is to wind down the relationship while retaining the assets created process maps, data flow diagrams, QA routines and using them to strengthen internal operations.
When is a 30 day pilot the wrong tool
A 30 day pilot is not the right tool when work is heavily dependent on long term relationships, deep domain expertise that cannot be learned quickly, or complex compliance regimes that require extensive design before any outsourcing. In those cases, leaders may need a longer discovery process, internal process redesign, or staged collaboration that precedes any live offshore delivery.
Designing Your Next Pilot With Less Risk
A well designed pilot is a leadership tool for clarifying how your systems and teams respond to external capacity. It brings structure to questions that are otherwise answered through opinion and anecdote. When the first 30 days are scoped and governed carefully, leaders gain a realistic view of fit without gambling brand or compliance.
If you are considering a pilot or want to revisit a previous attempt, start by defining the narrowest slice of work that passes the test of being repeatable, rules based, and measurable. Align internal stakeholders around data boundaries, metrics, and governance cadence, then decide what success and next steps look like before anyone takes a live call or ticket.
When you are ready, invite our team to walk through a compliance first assessment of your current stack, customer journeys, and operational goals. Together we can design a 30 day outsourcing pilot that respects your data boundaries, aligns with your processes, and gives you the visibility you need to make informed decisions about long term customer experience and support delivery.